Enterprise
Lower AI cost across the whole company, without lowering quality
For companies where AI spend now runs across engineering, product and operations, and keeps climbing. We sit with each team, learn its setup and build a proxy tuned to it: up to 70-80% lower AI cost, same tools, same quality. The free bill review tells you your number before you commit.
Address for all your AI traffic: every tool, agent and model behind one proxy
Price gap per token between Claude Opus 5.5 and Haiku 5.5, prompts up to 100k tokens (Anthropic pricing, Oct 2026)
Off input and output on batch work that can wait (Anthropic and OpenAI pricing pages)
Works with any harness your team already uses
why proxen
Why enterprise AI bills grow faster than anyone planned
Coding agents and API usage are billed per token, and every team sets things up its own way. Most of the bill is waste nobody sees on the invoice. Here is what changes when the proxy is built for each team.
Tuned team by team, not one default for everyone
An engineering team pays for long agent sessions and cache rebuilds. A product team pays a top model to answer easy questions. An operations team runs bulk jobs at full price. We read each team's usage and set the levers that matter for it, so each saving fits the work.
Same quality, checked on your own work
Every rule is tested on the team's own work before it goes live, and the team lead approves it. Hard tasks keep the strongest model. The log shows which model answered every request, so anyone in the company can check.
Done with you, nothing to re-learn
We connect the API accounts your company owns (or help you open them) and point each team's tools at one address: Claude Code, Codex, Cursor, SDKs or your own agent harness. Every team keeps the tools it already uses.
What an enterprise gets: a smaller bill, and control of what is left
 Illustrative example
 Illustrative example
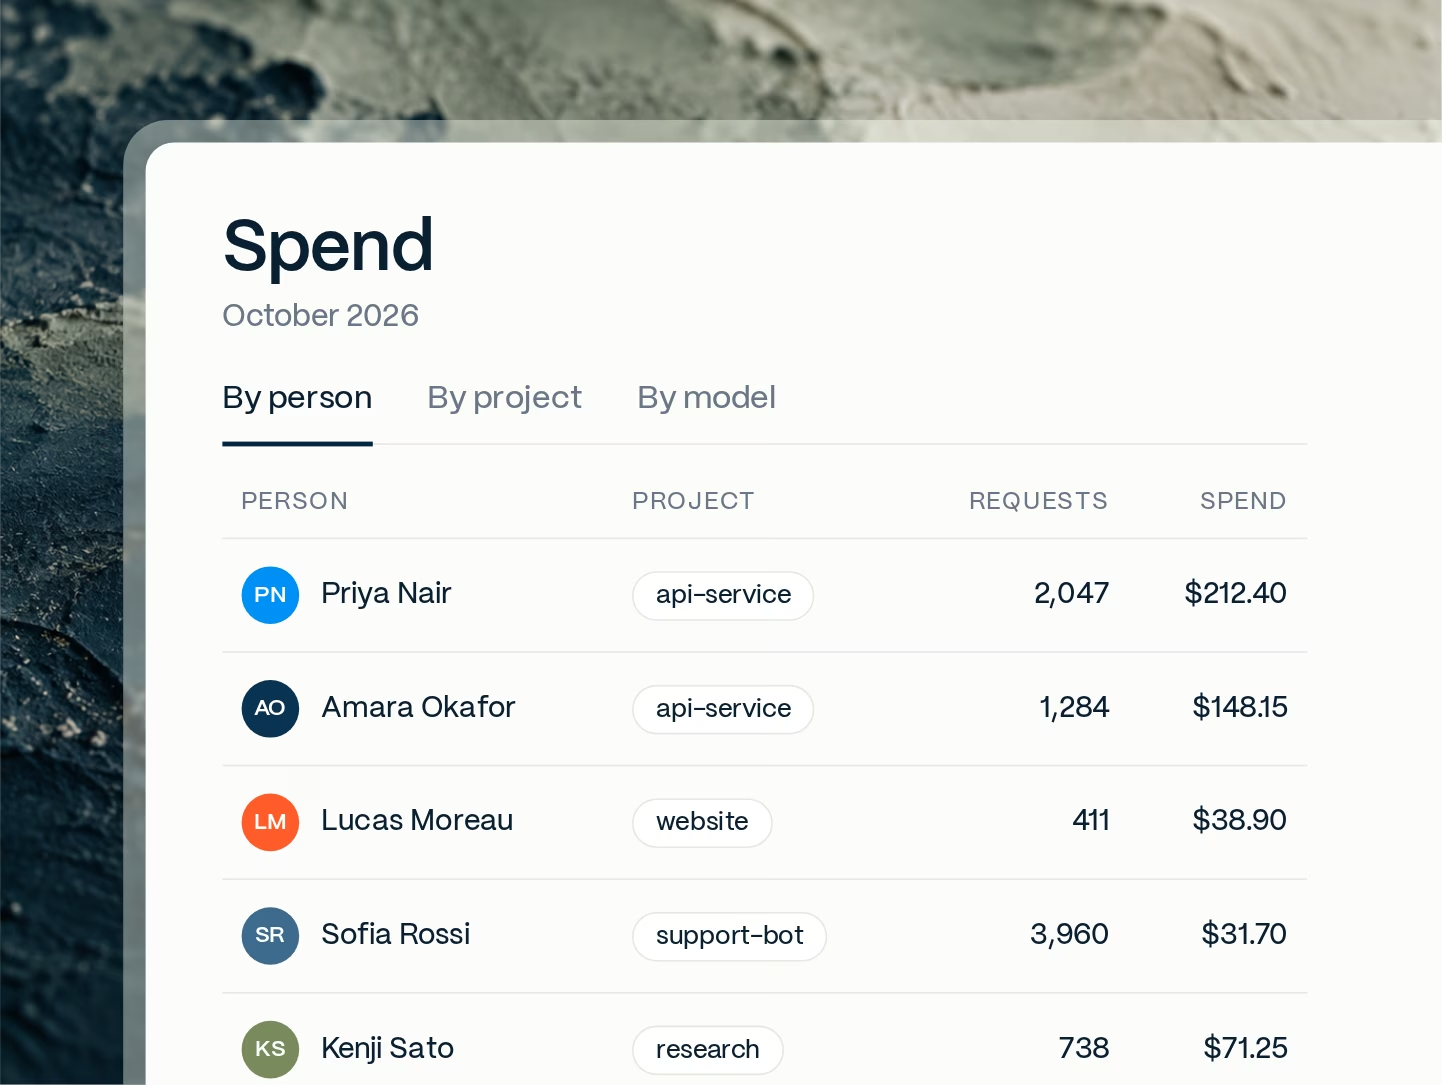 Illustrative example

One proxy, built for each team
Large companies rarely have one AI setup. Engineering runs coding agents, product teams call models from their code, and operations runs bulk jobs. Each one wastes money in a different place, and one company-wide setting cannot fix all of them.
So we work team by team. We read each team's usage, sit with its engineers, and tune the proxy for its work: how much history to trim, which tasks go to which model, what to cache and what can wait for batch. Quality is checked on the team's own work before anything changes.
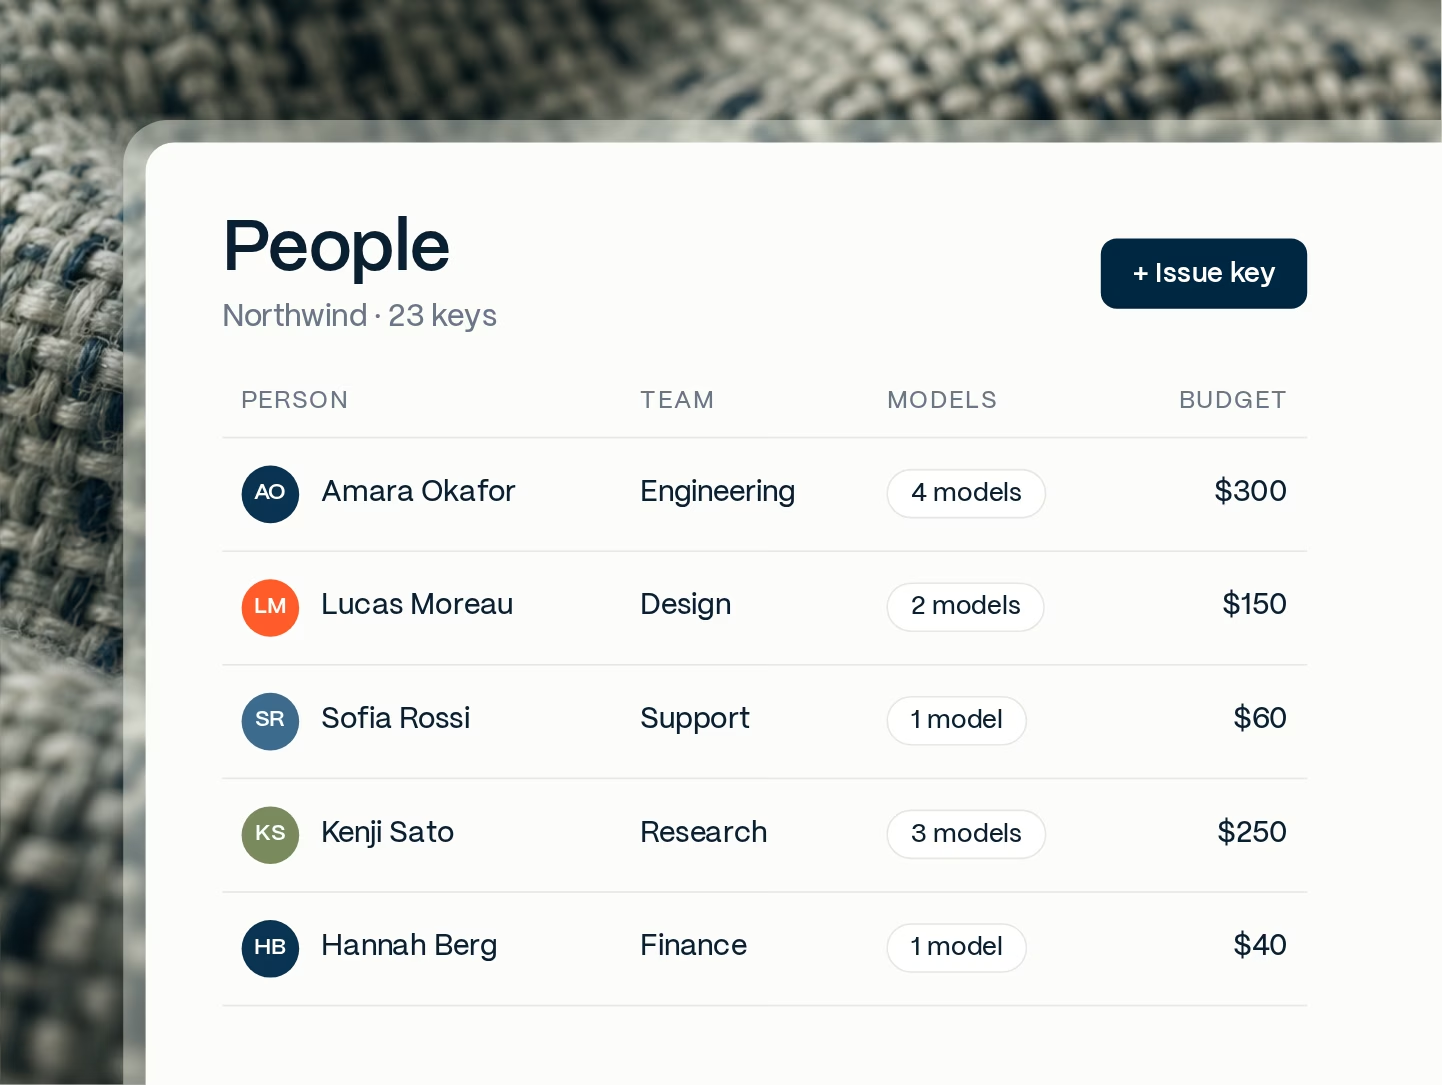
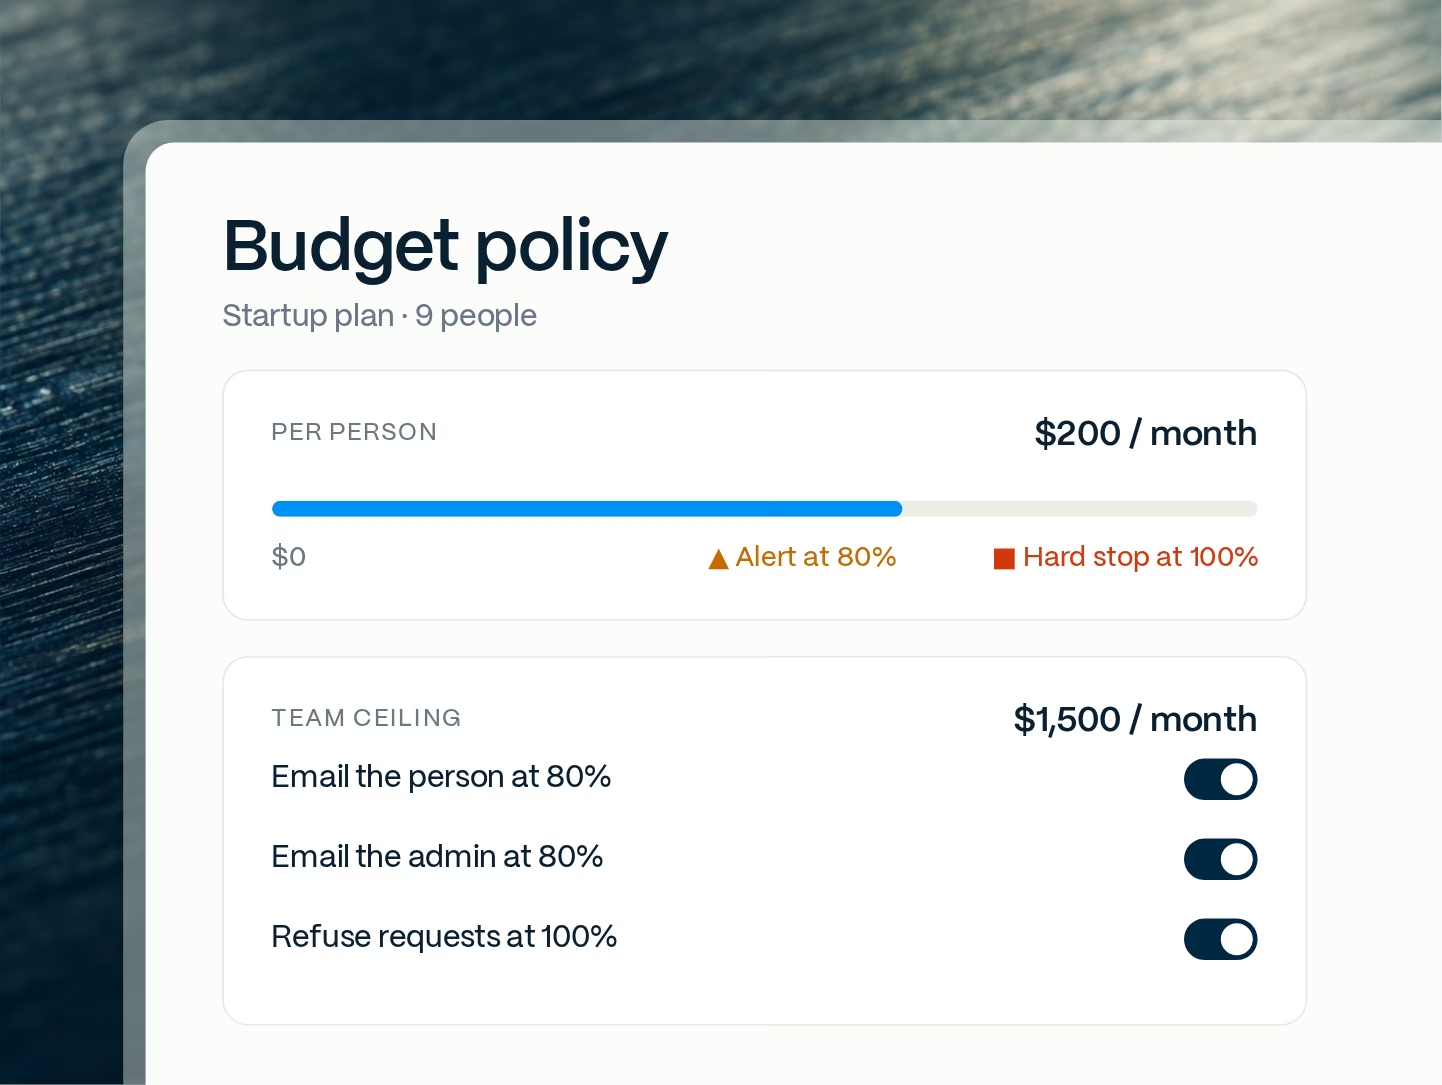
Everything runs on API accounts your company owns, in our cloud or yours. Each person and agent gets its own key, budget and log, so the saving shows up per team and per tool, not as one lump.
What a pilot looks like
Start with a free bill review, then one department. We agree the baseline, sit with the team, build the proxy for its setup and point its tools at one address. Quality is tested on the team's own work. At the end of the pilot you see the real saving on your own traffic, by person and project, and a rollout plan for the rest. See how the pilot works.
The provider key stays server-side; developers hold gateway credentials instead.
Find out what your company's AI bill should be
Send us one month of usage. We show you where the money leaks, team by team, and what you can expect to save. Free.